Something breaks in Salesforce again, and someone in the room finally asks the question that’s been circling for months: do we scrap this and start over? It’s a fair question. It’s also usually asked too early, before anyone in the room actually knows what’s wrong.
That gap matters. Rebuild an org that only needed cleanup, and you’ve spent months and a serious budget replacing something that was fixable. Patch around a foundational architecture problem instead, and you’ll be back in this same meeting next year, older and more frustrated, with a longer list of workarounds holding the thing together.
Rebuild an org that only needed cleanup, and you’ve spent months replacing something that was fixable.
Most teams don’t know which situation they’re in when they ask the question. That’s exactly what an audit is for.
The real distinction: repairable vs. structural
Not every messy Salesforce org needs to be torn down. And not every org that “sort of works” is actually fine underneath. The difference comes down to where the problem lives.
Repairable problems are governance and configuration debt. Ownership is unclear. Data is messy but not corrupted. Adoption is inconsistent. Automations are tangled but still functional. Nobody has ever mapped how the pieces connect, so small changes feel riskier than they are, but the underlying structure can hold.
Structural problems live in the architecture itself. The data model was built around a business that no longer exists: an old billing structure, an org chart that got reorganized twice since setup, a sales motion that’s changed completely. Every small change breaks two other things. The foundation, not the configuration on top of it, is what’s fighting you.
These require different fixes, at very different price points, and guessing wrong is expensive in either direction.
What a Salesforce Audit actually tells you
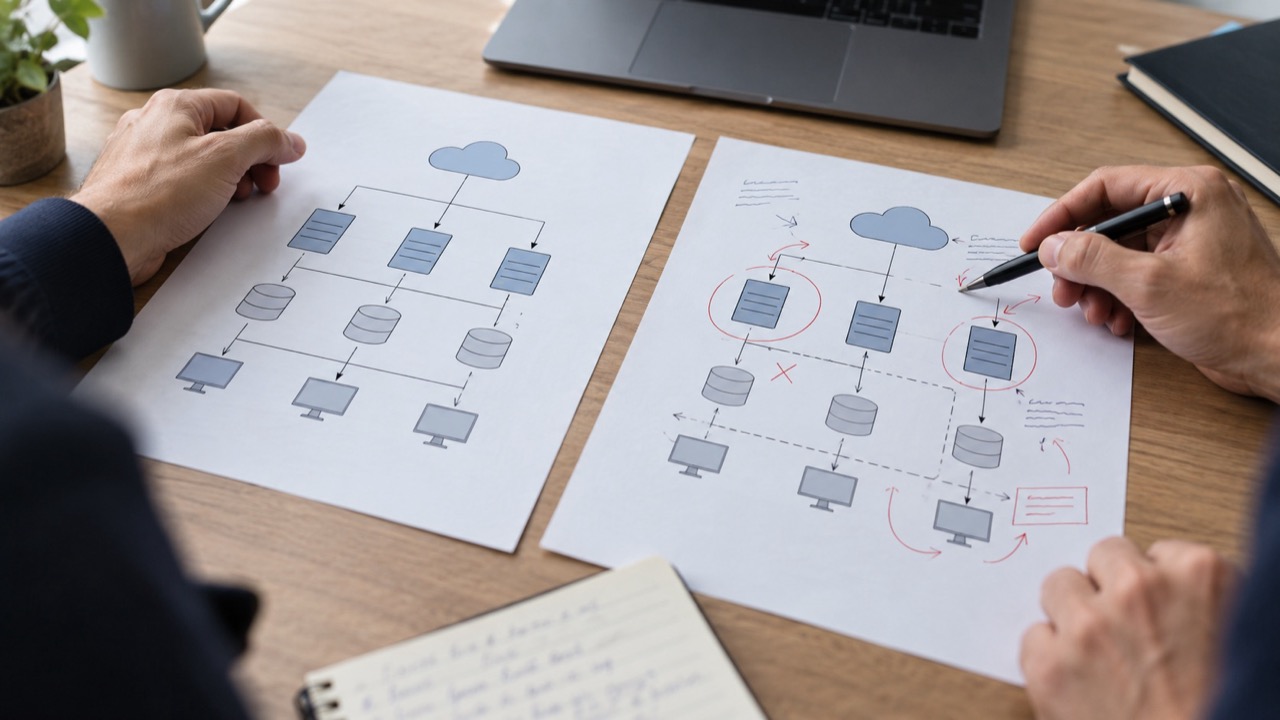
A Salesforce Audit is a senior-architect review of your automations, code, data model, security, adoption, and integrations, resulting in scored findings and a prioritized roadmap. It isn’t a sales pitch for a rebuild, and it isn’t a rubber stamp that everything’s fine. It’s the diagnostic step that tells you, with evidence instead of a gut feeling, which category your org actually falls into.
That distinction is the entire point. Without it, you’re deciding blind.
Signs you’re actually looking at a reimplementation
- Core objects were built around a business model the company doesn’t run anymore
- The data model conflicts so badly with current process that fixes require workarounds stacked on other workarounds
- Nearly every change ripples into two or three unrelated breakages, because the dependencies were never designed with any separation
- Leadership has lost trust in the platform broadly, not just in one feature or report
If dependency mapping shows that touching one field routinely breaks flows in three unrelated places, that’s not a configuration problem you clean up in an afternoon. It’s a sign the foundation itself needs to change, which is exactly the kind of risk the Change Impact Analyzer is built to expose before a project starts, not after it breaks something in production.
Signs you’re actually looking at an audit-and-fix
- Adoption is inconsistent, but the underlying object structure still reflects how the business runs today
- Data is messy, duplicated, or incomplete, but not fundamentally miscategorized
- Nobody owns changes, and there’s no documentation, which is a governance gap, not a design flaw
- Automations are tangled and hard to trust, but they’re tangled because they accumulated without oversight, not because the data model beneath them is wrong
Here’s a composite example based on patterns we see often, not one specific client. A founder is convinced the org needs to be scrapped. It “just feels broken.” Deals stall in weird stages. Reports contradict each other. Every conversation about fixing it turns into a conversation about starting over instead.
The audit finds something different. The core data model is sound. Accounts, opportunities, and the relationships between them still reflect how the business actually sells. The real problem is three years of undocumented automation bolted on one exception at a time, each one reasonable on its own, none of them documented, all of them now fighting each other. That’s a cleanup project, not a rebuild.
That pattern is well understood in the Salesforce architect community. Writing for the Salesforce Architects publication, Ian Gotts names poor documentation as the number one cause of technical debt: when nobody knows why a piece of metadata exists or what depends on it, it becomes too risky to change or remove, so teams build new pieces around it instead. From the outside, that looks like an org beyond saving. Underneath, it is often an org nobody has mapped.
An org that looks beyond saving is often just an org nobody has mapped.
The cost of skipping the diagnosis
Guess wrong in either direction and it costs you. Reimplement an org that only needed cleanup, and you’ve paid for months of rebuild work, disrupted the team through a second migration, and likely recreated some of the same undocumented shortcuts in the new org, because the habits that created the mess in the first place didn’t change. Patch around a structural problem instead, and you’re funding the same fire every few months, each fix a little more expensive than the last, until the “quick patch” budget quietly exceeds what a real rebuild would have cost two years ago.
Neither mistake is really about Salesforce. Both are about making an expensive, foundational decision without the evidence to back it.
What to do next
Don’t start with a vote in a leadership meeting about whether to rebuild. Start with a Salesforce Audit. It’s built to answer exactly this question, with a scored, prioritized view of what’s actually wrong, so the decision that follows is based on your org, not on how frustrated the room felt that week.